Track C, rung C5 (Voronoi methods plan): the distributed static solvers — the ghost field exchange over VoronoiHalo (core's ORB decomposition + particle halo) and the global reductions, installed on CollocatedNS / PressureSolver through their hooks. More...
#include <mpi.h>#include <Kokkos_Core.hpp>#include <type_traits>#include <vector>#include "peclet/voro/fv/operators.hpp"#include "peclet/voro/mpi/voronoi_halo.hpp"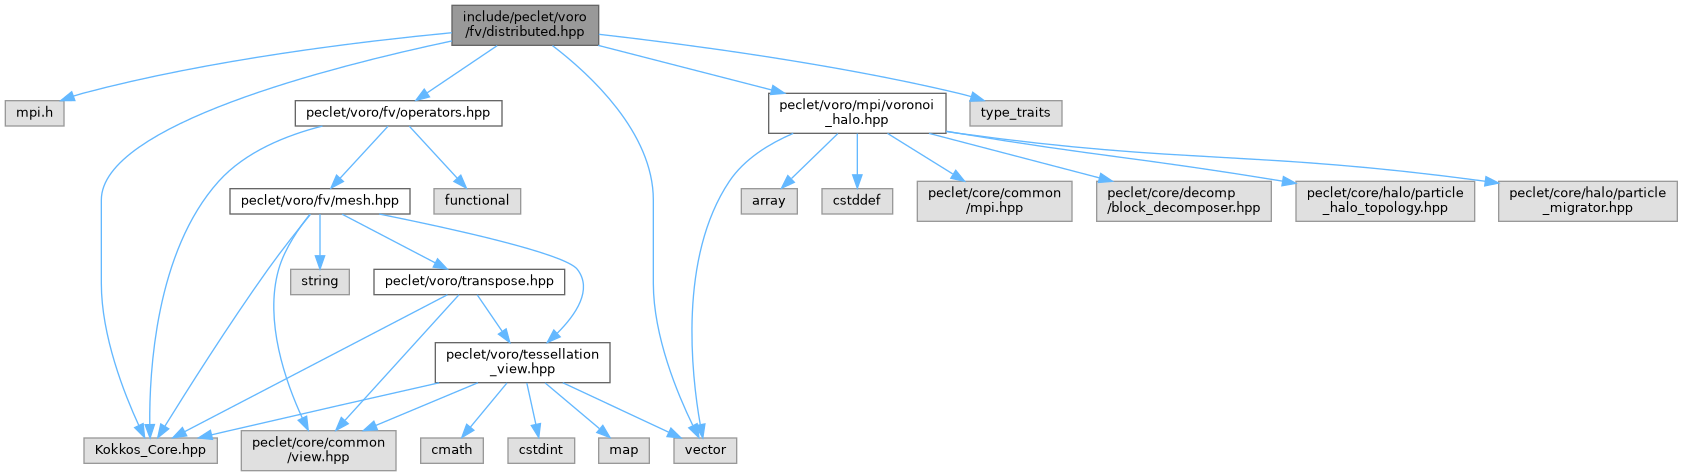
Go to the source code of this file.
Classes | |
| struct | peclet::voro::fv::GhostExchange< Real > |
Namespaces | |
| namespace | peclet |
| namespace | peclet::voro |
| Device-native Voronoi tessellation, geometry and finite-volume physics. | |
| namespace | peclet::voro::fv |
Detailed Description
Track C, rung C5 (Voronoi methods plan): the distributed static solvers — the ghost field exchange over VoronoiHalo (core's ORB decomposition + particle halo) and the global reductions, installed on CollocatedNS / PressureSolver through their hooks.
Layout: this rank's tessellation is built for its owned seeds [0, nOwned) with the gathered ghost seeds [nOwned, nCombined) as candidates (DistributedMovingTessellation's layout); the face mesh (buildFaceMesh(view, aux, nOwned)) keeps the facets toward ghosts as INTERFACE faces owned here. Cell fields are sized nCombined; the owned part is stepped, the ghost part is refreshed from the owning ranks by exchange (VoronoiHalo::forward over the established topology) — velocity, its gradient, the pressure, the transpose moments — so an interface face computes the same flux on both ranks from identical inputs. Pressure PCG: the matvec exchanges the search direction, the dot products are all-reduced, the AMG preconditioner is the per-rank owned block (block Jacobi). np = 1 is the single-rank code path (no ghosts, identity hooks).
The exchange packs on the device (gather kernel over the flat topology's send list) and scatters the receives into the ghost slots on the device; only the packed buffers cross to the host for MPI (host-staged, like core's GPU-resident GridHalo variant). CUDA-aware MPI on the device buffers is the remaining step.
